Storage for HA in Proxmox VE#
If you’ve already gone through my article on building a Proxmox cluster - QDevice, quorum, mixed hardware across nodes - you’ve probably run into the obvious next question: where exactly are your VM disks supposed to live for that whole automatic-restart setup to actually work, rather than just look good in the UI? It’s not a hypothetical concern - I’ve seen plenty of people set up HA, click around to confirm “yep, works,” and then lose data the moment the wrong node actually goes down, because the VM’s disk was only ever sitting on that one node in the first place.
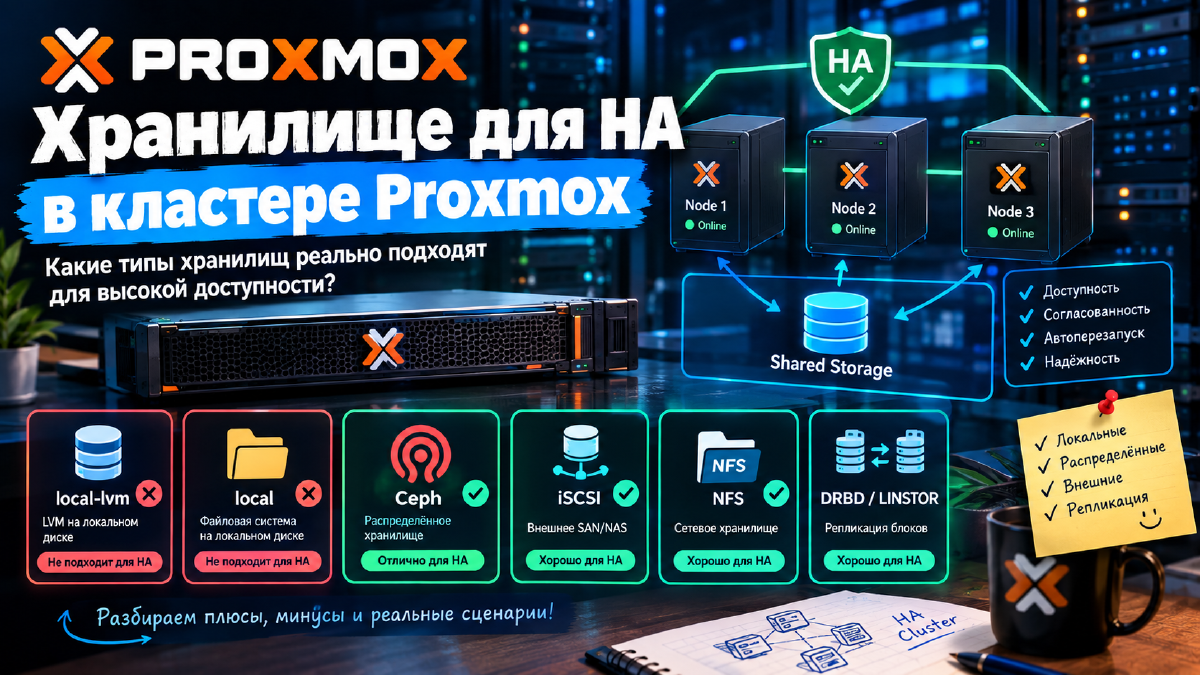
In this article and video, I go through which storage types in Proxmox genuinely qualify for HA, which ones just resemble shared storage right up until the moment they let you down, and what to pick depending on how many nodes you’re running.
If this article helped you out, you can support the author by becoming a sponsor on Boosty (also linked in the contacts section).
Table of Contents#
- The role of storage in High Availability
- Single node + HA requirement
- Two nodes + quorum / witness
- Three or more nodes with shared storage
- Hyperconverged storage: Ceph and alternatives
- External SAN/NAS options
- What doesn’t work for HA at all
- Recommendations
- Wrapping up
1. The role of storage in High Availability#
In a Proxmox VE cluster, High Availability (HA) is supposed to automatically restart VMs and containers on another node when the original one goes down. Sounds simple, but the whole thing hinges on exactly one thing: what kind of storage the VM’s disk actually lives on.
When a node drops, a neighboring node needs to be able to:
- reach the failed VM/CT’s disk immediately - no copying files over, no “hang on, let me sync this first”;
- read the current, correct configuration;
- boot the VM without any risk of data getting out of sync - meaning no chance of starting it against a stale copy of the disk while a newer one exists somewhere else.
If the storage is physically tied to the node that just died (a plain local disk, thin-LVM on a local SSD, whatever) - that’s it, game over. You don’t even need to bother configuring HA past that point, because it simply can’t work: the neighboring node has no way to pull a disk out of a dead server.
What storage needs to be capable of for HA#
- Shared access - the VM’s disk is physically reachable from multiple nodes at once, not copied there “just in case.”
- Cluster-level consistency - locking, split-brain protection, and replication that’s synchronous or close enough to it.
- Failover with zero manual steps - Proxmox starts the VM on another node by itself, not “let me go mount that disk real quick.”
- A dedicated storage network - keep storage traffic separate from management/VM traffic where you can; 10GbE or better is worth aiming for, especially with Ceph.
- Reliability at the data layer - RAID, Ceph replication, DRBD, a genuinely redundant NAS/SAN - something that survives a single disk failure too, not just a node failure.
- Actual support in Proxmox’s own HA stack - Ceph, iSCSI, NFS, ZFS replication. I’m leaving GlusterFS off that list on purpose - more on why below.
GlusterFS as a built-in Proxmox storage type is no longer supported as of Proxmox VE 9 - the Proxmox team’s own stated reason is that GlusterFS itself isn’t really moving forward upstream anymore. It still works on Proxmox VE 8 for now (8.x support runs for roughly a year past the 9.0 release), but I wouldn’t build anything new on it. You can technically still mount a Gluster volume yourself and add it as directory storage, but at that point you’ve lost the native HA-stack integration and you’re on your own.
2. Single node + HA requirement#
I still run into people genuinely confused about why HA won’t work on a single box. Let’s walk through the four setups people usually try first, and why none of them get you there:
2.1. Local storage (ZFS RAID or hardware RAID)#
The upsides are obvious: protection against a single disk failing, simplicity, solid performance. There’s exactly one downside, and it’s fatal for our purposes: failover is flat-out impossible, because the entire array physically lives inside one chassis. The server goes down, and the RAID array goes down right along with it.
2.2. ZFS replication to a “passive” node#
Proxmox’s ZFS replication copies disk snapshots to a neighboring node on a schedule (minutes at best, not seconds). That gets you a cold standby - in a real outage, you can manually spin the VM up on the second node, losing whatever changed since the last replication run. That’s not HA: there’s no automatic startup, recovery is a manual step, and you lose everything written after the last snapshot.
2.3. Replication to an external NAS#
Fine for backups, but the NAS itself now becomes an SPOF (single point of failure) - you haven’t removed the risk, you’ve just relocated it to a different box.
2.4. Snapshots + vzdump#
This is backup, not HA. Recovery is possible, but it’s neither automatic nor instant - by the time you’ve restored from backup, the service has already been down, which entirely defeats the point of High Availability.
Bottom line: HA is physically impossible on a single node, full stop. The floor is two nodes with genuinely shared access to storage - and even that comes with a catch, as we’re about to see.
3. Two nodes + quorum / witness#
3.1. The two-node problem: split-brain#
With just two nodes, if the link between them drops, each one sees the situation as “I’m the only one still alive, the other one must be dead” - and both can try to bring up the same VM at once. That’s classic split-brain, and cluster quorum is exactly what’s supposed to prevent it. The catch is that two nodes can never form a real quorum on their own - it’s 1 vote against 1 vote, and a majority never emerges from that.
I covered the quorum mechanism itself - votes, thresholds, all of it - in the article on building a Proxmox cluster. Short version here: you need a third vote.
The fix: QDevice#
A QDevice is an external “referee” - it doesn’t store or run VMs, it just gets a say in the vote. There’s a lot of flexibility in where you put it: a lightweight standalone VM, a mini PC, a Raspberry Pi, even the same Proxmox Backup Server box if you already have one. Once that third vote exists, the cluster can form a real majority again (2 out of 3), and HA starts behaving the way you’d expect.
3.2. Storage options for a 2-node cluster#
| Storage | Fit for HA | SPOF | Needs QDevice | Performance |
|---|---|---|---|---|
| ZFS Local + Replication | Partial (data loss up to the replication interval) | Node | Yes | Medium |
| NFS / iSCSI / NAS | Yes | NAS/SAN | Yes | Medium |
| Ceph | Yes | None (with 3+ monitors) | Yes | High |
| DRBD9 (via LINSTOR) | Yes | None | Yes | Medium |
DRBD9 isn’t a built-in Proxmox plugin. It runs through a separate LINBIT product called LINSTOR (plus the linstor-proxmox plugin), which you install and configure entirely separately from Proxmox itself. LINBIT’s public package repo is free to use for a homelab or testing, but comes with zero SLA or support guarantees - for production, LINBIT explicitly points you at their paid customer repositories instead. So “DRBD9” in the tables above isn’t “comes with Proxmox” - it’s “one more piece of infrastructure you’ll be standing up and maintaining yourself.”
One thing worth flagging specifically for Ceph on two nodes: Ceph’s own monitor quorum (ceph-mon) needs an odd number of votes, and two nodes don’t give you that. In practice, people running this setup stand up a third Ceph monitor on some external box (the same QDevice host, say) - just for monitor voting, with no actual OSDs attached to it.
4. Three or more nodes with shared storage#
4.1. Why three nodes suddenly makes everything easier#
With three nodes, quorum just works natively, no workarounds needed: a majority is 2 out of 3, split-brain from losing a single node is arithmetically impossible, and no QDevice is required anywhere. HA groups configure the normal way through the UI, no extra hoops.
4.2. Shared storage - file-based and block-based access#
NFS#
File-based storage, works fine for both VM/CT disks and ISOs/templates. Takes about two minutes to set up:
Datacenter → Storage → Add → NFS
Server: your NAS's IP
Export: /volume1/proxmox
Content: Disk image, ISO image, Backup
Nodes: every node in the cluster
The catch: the NAS itself is an SPOF. If it goes down, every VM whose disk lives on that NFS share goes down with it, regardless of how many Proxmox nodes you’re running.
iSCSI#
Block-based rather than file-based access, and it outperforms NFS. For HA, multipath is non-negotiable - multiple independent network paths to the target - otherwise one dead network link takes down disk access just as reliably as a dead node would.
Datacenter → Storage → Add → iSCSI
Portal: your SAN's IP
Target: the IQN you need
Nodes: every node in the cluster
Optional: LVM over iSCSI - if you want snapshots and thin provisioning
Same risk as NFS: an SPOF on the SAN side, unless the SAN itself is redundant.
SMB/CIFS#
Good only for ISO images and container templates. VM disks flatly don’t work over SMB - Proxmox won’t even let you add it as storage for disks in the first place.
4.3. A quick comparison on performance and risk#
| Architecture | SPOF | Performance | Requirements | Scalability |
|---|---|---|---|---|
| NFS | NAS | Medium | Low | Medium |
| iSCSI | SAN (if not redundant) | High | Medium | Medium |
| Ceph | None | High | High (network, disks, nodes) | Excellent |
Ceph stands out here for more than just good numbers on a table - it’s the only option of the three that, set up correctly, has no single point of failure at all: data is spread across every node instead of sitting on one external box.
5. Hyperconverged storage: Ceph and alternatives#
Hyperconverged here means storage and compute live on the same cluster nodes, with no separate NAS/SAN as a standalone device.
Ceph is the most mature option of this kind in the Proxmox ecosystem: RBD volumes for VM disks, CephFS for ISOs, templates, and backups. Data gets spread across nodes and can self-heal when a disk or a node fails. The price of entry: at least 3 nodes, a dedicated network for Ceph traffic, and ideally SSD/NVMe rather than spinning disks - Ceph on HDDs is a special kind of pain that anyone who’s tried it can tell you about.
If you’re reading this as the owner of a 2-3 node homelab and already thinking about spinning up Ceph “just to have it” - read my separate article, Why I Don’t Need Ceph Storage in Proxmox for a Home Server, first. Ceph is a deliberate choice for infrastructure where HA genuinely matters, not a default “correct” answer for everyone.
The spiritual alternative to Ceph (not a like-for-like replacement) is the same DRBD9/LINSTOR setup covered in the two-node section above - it just scales to 3+ nodes too.
6. External SAN/NAS options#
| Type | Description | Fit for HA | Note |
|---|---|---|---|
| NAS (NFS) | File-based storage | Yes | Works for both VM disks and ISOs |
| NAS (SMB/CIFS) | File-based storage | ISOs/templates only | VM disks won’t work over SMB |
| SAN (iSCSI/Fibre Channel) | Block-based access | Yes | Multipath is mandatory |
| Unified Storage (NFS + iSCSI) | Combined | Yes | The NAS/SAN itself needs to be redundant on its own side |
The core point of this whole section, said a third time on purpose: your Proxmox cluster’s HA will never be more reliable than the single box your VM disks actually live on, if that box has no redundancy of its own. A five-node Proxmox cluster backed by one non-redundant NAS is HA with one enormous SPOF sitting right behind it.
7. What doesn’t work for HA at all#
| Storage | Fit for HA | Why |
|---|---|---|
| Local LVM / Directory | No | Visible from a single node only |
| CIFS/SMB | No | ISOs/templates only, not VM disks |
| Local ZFS without replication | No | Needs at least replication, ideally real shared storage |
| Rsync / manual replication | No | No automatic failover, everything is manual |
If your current storage is one of these and HA still shows as “enabled” in the Proxmox UI - it’s only enabled on paper. There’s no real failover behind it, and you’ll find that out at the worst possible time.
8. Recommendations#
Boiling the whole article down to something actionable:
- 3 nodes minimum for real quorum without a QDevice - two nodes can work, but only with a clear understanding that a third vote has to come from somewhere regardless.
- Use shared or hyperconverged storage - no “local disks and hope for the best.”
- A dedicated network for storage traffic, ideally 10GbE, especially with Ceph.
- Set up HA groups deliberately, not “flip the checkbox and forget about it.”
- Regular backups through Proxmox Backup Server - HA protects you from a node dying, not from a mistake inside the VM or from corrupted data.
- Actually test failover by hand every so often - deliberately power off a node and watch what happens. An unpleasant surprise during a test beats one at 3am in production.
- Synchronous replication for anything genuinely critical, not “a snapshot once an hour.”
- Document the architecture - six months from now, you won’t remember why you set it up this particular way.
9. Wrapping up#
To sum it up: on a single node, HA simply doesn’t exist. On two nodes, you need a QDevice (and, with Ceph, a separate third monitor on top of that). From three nodes on, quorum handles itself, and that’s really where predictable HA begins. Which specific storage - Ceph, DRBD9/LINSTOR, NAS/SAN - comes down to your budget and your actual needs, not “everyone else uses it, so I should too” (GlusterFS is a pretty good cautionary tale about betting on a fading project - as of Proxmox VE 9, it’s simply not there as a built-in option anymore).
What’s covered here is the foundation. From here, it’s about testing failover on a live cluster, monitoring, and growing the setup’s complexity gradually as your infrastructure actually needs it - not upfront.